Reply Better AI rewrites a message in the tone you pick. Its default model is Claude Haiku 4.5. I wanted to know if that is still the right choice, so I measured it instead of guessing.
The setup. I wrote 30 drafts like the ones people really send: client emails, quick Slack messages, Turkish and English, typos left in, most with a date, an amount or a link. Each draft ran in two styles, “improve” and “professional”, on five models. That is 300 rewrites.
A stronger model, Claude Sonnet 5.5, graded every rewrite from 1 to 5 on four things: is the meaning kept, does the tone fit the style, does it sound like a person, and is the length right. Simple code checked the rest: numbers and links kept, no “Here’s your message:” at the start, and no switch to another language.
What came out.
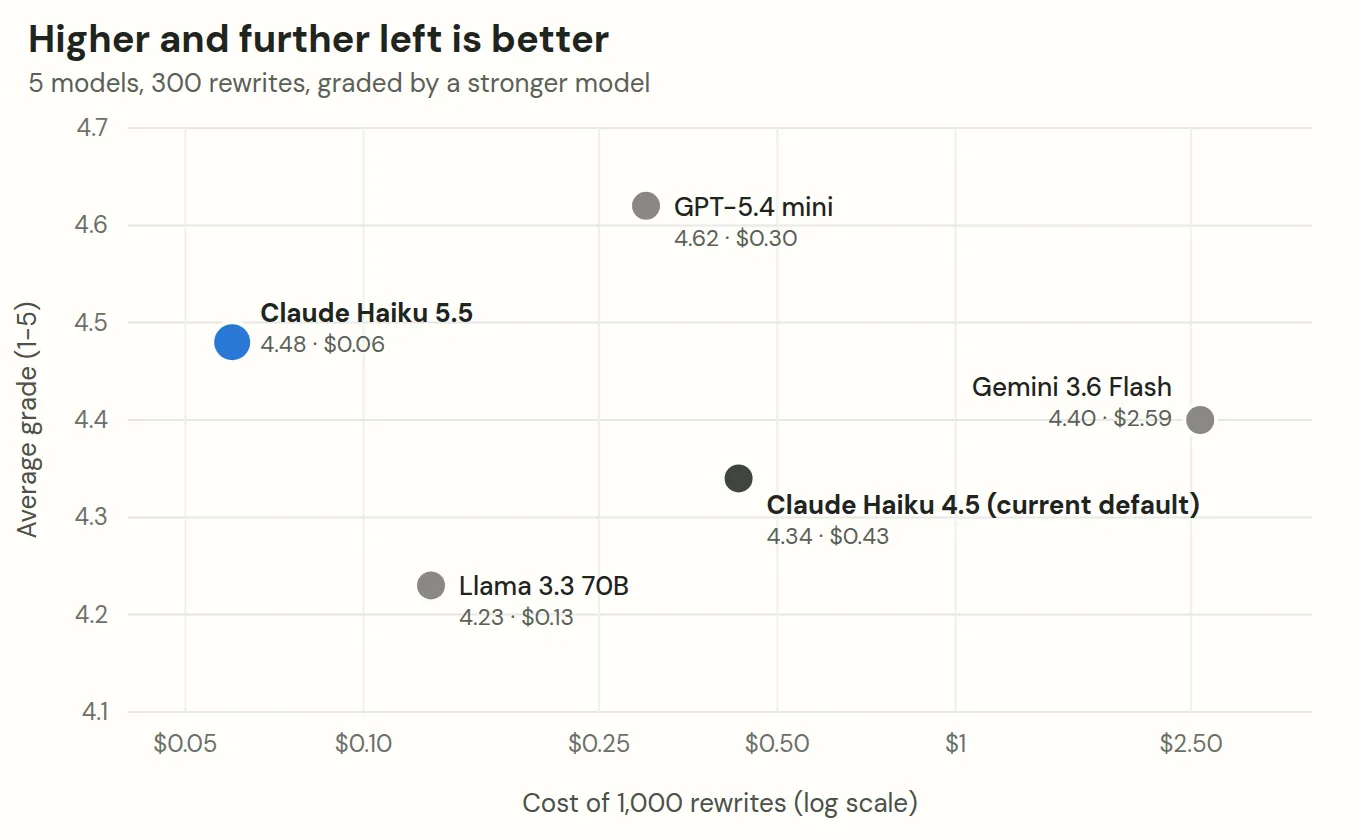
The same numbers as a list, average grade then the cost of 1,000 rewrites:
- GPT-5.4 mini: 4.62, $0.30
- Claude Haiku 5.5: 4.48, $0.06
- Gemini 3.6 Flash: 4.40, $2.59
- Claude Haiku 4.5, the current default: 4.34, $0.43
- Llama 3.3 70B: 4.23, $0.13
The surprise
The cheapest model scored higher than the current default overall, and it costs about seven times less.
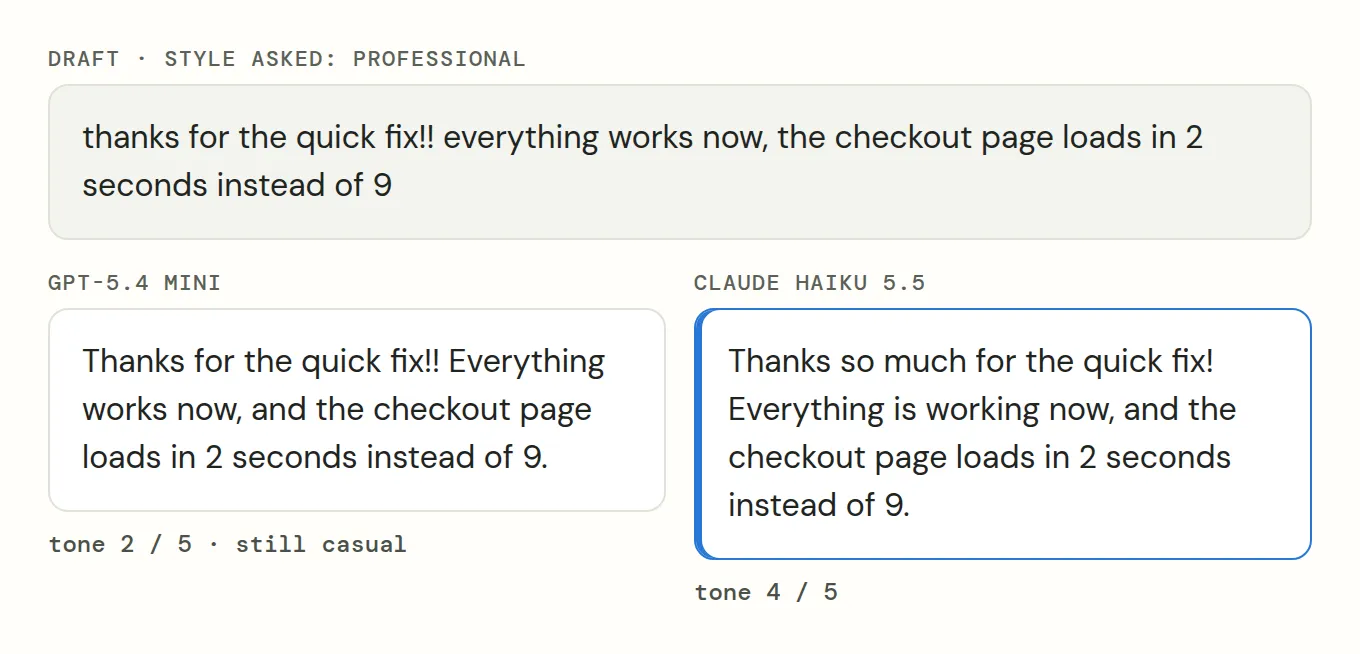
GPT-5.4 mini wrote the most natural text, but when I asked for “professional” it mostly fixed capital letters and left a casual message casual.
Gemini spent hidden “thinking” on a simple rewrite, so it was the slowest (5 seconds) and the most expensive. Llama 3.3 turned relaxed drafts stiff and formal.
What it cost. The rewrites cost well under a dollar. Grading cost about ten times more, because every rewrite gets five judge calls. I also burned credits on a rerun I expected to retry only the failed cases, but it ran almost everything again. Next time I’ll try the judge on a small set first.
The numbers have limits. Sixty cases is a small set, and a Claude model grading Claude models may be a little biased. GPT still came first, so I don’t think it changed the result.
The takeaway
Measure before you pick a model. Price and quality don’t always move together, and the grading is the expensive part.